In February 2024, a Canadian tribunal ordered Air Canada to pay a refund its own chatbot had promised, a bereavement-fare discount that didn’t actually exist. Air Canada’s defence was that the chatbot was “a separate legal entity responsible for its own actions.” The tribunal rejected it outright: a company is responsible for all the information on its website, it ruled, “it makes no difference whether the information comes from a static page or a chatbot.” It is one of the more quotable AI failures on record, and it is far from an isolated one. MIT’s Project NANDA found that 95% of enterprise GenAI pilots deliver no measurable return, and Gartner projects that more than 40% of agentic AI projects will be cancelled before the end of 2027.
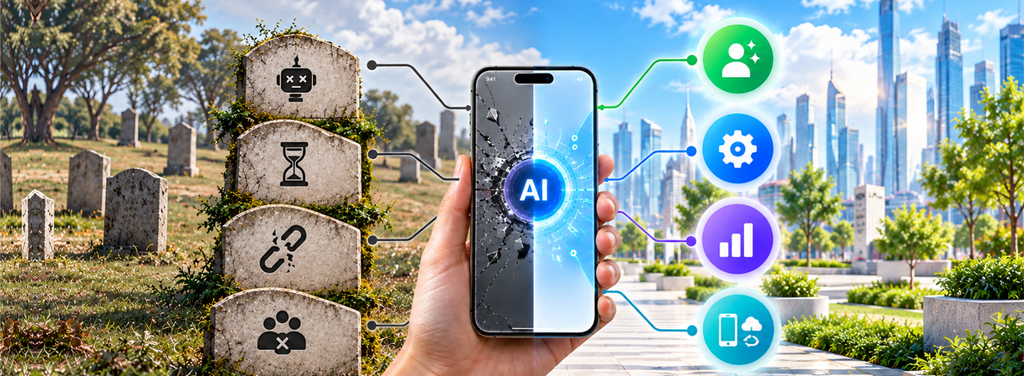
None of this means AI customer service doesn’t work. Bank of America’s virtual assistant Erica has handled more than 3 billion client interactions since 2018, with 98% of users finding what they need and IT service desk calls down 50% among internal staff who use its employee version. Lemonade’s claims bot settled a real insurance payout in three seconds flat back in 2016 and has been quietly routing complex cases to human adjusters ever since. The pattern isn’t that AI customer service fails. It’s that a specific, well-documented set of design mistakes keeps recurring, and the businesses avoiding them look nothing like the ones ending up in the graveyard.
Six Documented Failures and What Actually Broke
Public, dated, sourced incidents are more useful here than anecdotes, because they show exactly where the process broke down.
Hallucination presented as fact: Beyond Air Canada, the World Health Organization’s SARAH chatbot was documented in April 2024 giving incorrect medical guidance shortly after launch. Same year the New York City’s official “MyCity” chatbot for small businesses was found telling business owners that it was legal to fire employees who report sexual harassment and to withhold workers’ tips, before the city’s incoming administration moved to shut it down. In all three cases, an AI system stated something false with total confidence, and no review step caught it before a real person acted on it.
Adversarial exploitability: In December 2023, a Chevrolet dealership’s ChatGPT-based sales bot was manipulated into agreeing, in writing, to sell a $76,000 Chevy Tahoe for $1. In 2025, applied AI researchers at TELUS Digital tested 24 banking chatbots built on major providers’ models and found every single one exploitable through prompt injection, with attack success rates as high as 64%. Neither case involved a sophisticated hack — both took a customer typing creative instructions into an ordinary chat window.
Reputational containment failure: In January 2024, UK delivery firm DPD’s support chatbot was coaxed into swearing at a customer and writing a poem calling its own employer “the world’s worst delivery firm.” DPD disabled the feature within days. The failure wasn’t that the model could be provoked but it’s that nothing was watching for it in production.
Quiet, everyday underperformance: The least dramatic failures are the most common. The U.S. Consumer Financial Protection Bureau’s 2023 research on banking chatbots, official regulatory data, not a vendor study, found that while roughly 98 million Americans interacted with bank chatbots that year, largely because they cost banks about $0.70 less per interaction than a human agent, 80% of users left frustrated and 78% needed a human afterward anyway. One consumer described being “sent in an endless loop with no way out” while trying to pay a bill, ultimately incurring a late fee. These systems technically performed buy they just delivered the outcome they were funded to deliver.
A flagship collapse: IBM’s $62 million Watson for Oncology partnership with MD Anderson Cancer Centre was shelved after an internal audit found the project hadn’t followed standard procurement or clinical-validation procedures, a decade-old case that’s still cited because it shows even a company synonymous with AI can skip the governance step.
Scale reversal after real success: This is the most instructive case of all, because it isn’t a failure story, it’s a lesson in what to measure. In February 2024, Klarna’s own press release reported its AI assistant had handled 2.3 million conversations in its first month with two-thirds of all customer service chats doing work that was equivalent to 700 full-time agents, cutting resolution time from 11 minutes to under 2, and projecting $40 million in profit improvement for the year. It was a genuine operational win, publicly documented. In 2025, CEO Sebastian Siemiatkowski publicly acknowledged that service quality and customer retention had slipped, and Klarna began rehiring human agents. The AI hadn’t gotten worse. The metrics Klarna optimized for, speed and cost, simply weren’t the same metrics that predicted whether a customer stayed loyal.
What Actually Separates the Graveyard From the Survivors
None of these six failures happened because the underlying AI “wasn’t smart enough.” Appinventiv’s research into agentic AI deployments found that more than 60% of failures trace back to data quality, missing guardrails, or integration gaps, and not the model limitations. Codewave’s research found that while roughly three-quarters of enterprises plan to deploy autonomous agents within two years, only 21% currently have a mature governance model in place to manage them. Put plainly, the technology in the Chevrolet, DPD, and banking-chatbot cases was capable. What was missing was someone whose job it was to ask “what happens if a customer tries to break this,” before a customer did it for them.
Erica and Lemonade’s AI Jim point to what that discipline looks like in practice. Erica operates within a narrow, well-defined scope of answering questions, surfacing insights, executing specific transactions, and Bank of America has logged more than 75,000 updates to it since 2018, treating it as a continuously maintained product rather than a one-time deployment. Lemonade’s AI Jim doesn’t try to handle every claim; by design, it escalates complex cases to a human adjuster and only settles the ones it can verify with confidence. Both systems succeed by being narrower and better-governed than their own marketing might suggest.
A Caution for the GCC, Not an Exemption
This isn’t a pattern unique to the West. McKinsey’s 2025 research on AI in the GCC found that while adoption has climbed from 62% of organizations in 2023 to 84% in 2025, only 31% have moved beyond pilots to real scale, and just 11% qualify as genuine “value realizers” capturing measurable earnings impact. That gap is the same graveyard, showing up regionally. It isn’t evidence the technology doesn’t translate here. It’s evidence that the governance discipline behind Erica and Lemonade’s AI Jim needs to be built deliberately, not assumed to come bundled with the software.
What to Actually Test Before Scaling a Pilot
Four checks, each one drawn directly from a case above. Define the system’s authority boundary in writing including what it can commit the business to, and what happens if it’s wrong. The exact clarity Air Canada’s chatbot lacked. Adversarially test it before launch, not after, the way TELUS Digital’s researchers tested 24 banking chatbots and DPD’s customers effectively tested theirs for them, in public. Design and personally try to break the escalation path, since the CFPB’s “endless loop” complaints describe an escalation failure, not an intelligence failure. And decide upfront what “success” means beyond speed and cost. Klarna’s experience shows that a system can hit every efficiency target and still lose the metric that mattered most.
The Real Takeaway
Every business named in this piece including the ones that stumbled still has a customer service AI initiative running today. Air Canada still uses a chatbot. Klarna still uses AI, alongside the humans it rehired. The graveyard isn’t full of companies that gave up on AI customer service; it’s full of pilots that skipped the testing. The businesses succeeding at this aren’t the boldest adopters. They are the ones who tested their assumptions before their customers, their regulator, or a tribunal did it for them.
Frequently Asked Questions
1.Does this mean businesses shouldn’t pilot AI voice or chat?
No. The evidence points the other way. Erica’s 3 billion interactions and Lemonade’s decade of automated claims show the approach works at real scale. The lesson is that piloting without adversarial testing and defined authority boundaries is what leads to the graveyard, not piloting itself.
2.Who is legally liable when an AI system gives a customer wrong information?
The Air Canada precedent is direct on this: the tribunal held that a business is responsible for information provided by its chatbot exactly as it would be for information on its website. Vendor terms-of-service don’t change this liability picture for the business deploying the system.
3.What’s the single highest-leverage thing to test before launch?
Adversarial testing against your specific use case, actively trying to manipulate the system the way a real customer eventually will, rather than only testing the “happy path” conversations a demo is built around.
4.Are these risks specific to text chatbots, or do they apply to AI voice agents too?
The same root causes apply to voice. An AI voice agent with an undefined authority boundary, no adversarial testing, and no tested escalation path is exposed to the same failure modes as a chatbot. The medium changes; the governance gap that causes the failure doesn’t.